When Dependencies Become Critical: A Dependency-Centric Perspective on Critical Infrastructure Resilience
Critical Infrastructure Protection (CIP) has traditionally organised resilience around identifiable assets and operators: determine what is critical, assess the risks they face, and strengthen their protection. This logic remains an important foundation of contemporary legislation, regulation and risk management.
The growing emphasis on essential services and functions has broadened this perspective. Their delivery increasingly relies on external platforms, suppliers, technologies and specialised capabilities that may lie beyond the ownership or direct control of the organisations responsible for them.
Contemporary resilience policy already reflects this broader perspective. The EU Critical Entities Resilience (CER) Directive focuses on the continuity of essential services and vital societal functions, while OECD work increasingly addresses resilience at the level of infrastructure systems and their interdependencies.
This article builds on these developments but asks a more specific question: what happens when the systemic significance of a dependency emerges across multiple organisations or sectors and may therefore not be fully visible from any single organisational perspective?
For the purposes of this article, a Critical Dependency is understood as a relationship, resource, service or capability whose disruption compromises the delivery of one or more essential societal functions, irrespective of its formal status within existing CI frameworks. The purpose of the category is not to rename dependencies, but to identify those whose systemic significance becomes visible only when reliance is considered across essential societal functions.
A dependency-centric perspective makes this intermediate level explicit: societal functions define what must be sustained; critical dependencies identify what must remain available; assets, services and capabilities determine how that availability is provided.
When Dependencies Become Systemic
Research on infrastructure interdependencies and systemic criticality has long demonstrated that the consequences of disruption are shaped by the position of assets within wider interconnected systems. A dependency-centric perspective builds on this insight by shifting attention to the relationship between a dependency and the functions that rely upon it.
Dependencies may acquire systemic significance through the structure of reliance around them. Reliance may be concentrated around a common provider or capability, extend across sectors, or connect organisations responsible for essential functions to resources they neither own nor directly control.
Dependency criticality arises not from the characteristics of a resource, service or capability alone, but from what depends upon it.
A service may appear non-critical when considered within a single bilateral relationship, yet acquire systemic significance when multiple essential functions rely upon it. Conversely, even an important dependency may have limited systemic consequences where realistic substitutes or alternative pathways exist.
This creates a problem of perspective. Existing assessments often examine dependencies from the standpoint of an individual organisation, function or essential service. A dependency-centric perspective adds an aggregate view by considering patterns of reliance across multiple functions, operators or sectors. Each individual organisation may reasonably conclude that a dependency is manageable, while the same dependency acquires systemic significance when these relationships are considered collectively. That significance may therefore exceed what is visible to any single participant in the system.
Asset criticality and dependency criticality are related but not identical. The systemic significance of a dependency derives from the functions that collectively rely upon it, rather than from its formal status or characteristics alone. Where that significance exceeds what individual actors can see, a dependency becomes more than an operational relationship: it becomes a distinct resilience concern.
What Makes a Dependency Critical?
The analytical challenge is to distinguish routine operational dependencies from those whose disruption could have wider societal consequences. Two considerations are particularly useful in assessing dependency criticality: how reliance is structured and what consequences disruption could produce.
The first concerns how reliance is organised around a dependency: how many essential functions depend upon it, how concentrated that reliance is, and whether realistic substitutes or alternative pathways exist.
The second concerns the consequences of disruption: the scale and severity of functional loss, and the potential for effects to propagate across infrastructures, sectors or societal functions.
These considerations interact. Concentrated reliance becomes more consequential where substitutes are limited and disruption can propagate across essential functions. No single characteristic is therefore sufficient to establish dependency criticality.
Dependency criticality is also contextual. The same service may be replaceable for one operator but indispensable for another. Its significance may change over time as technologies, markets, suppliers and operating conditions evolve. A capability with several viable substitutes today may become critical following market consolidation, technological integration or vendor lock-in. A routine dependency may also acquire temporary systemic significance during an emergency when alternatives are not immediately available or demand changes sharply.
Capacity adds another dimension to this problem. A dependency may be adequately available to individual essential services under normal conditions yet become constrained when several services require the same resource or capability simultaneously. Criticality may therefore arise not only from the absence of alternatives, but also from whether those alternatives—or the dependency itself—can meet aggregate demand under disruption.
Criticality should therefore not necessarily be understood as a permanent attribute of a dependency. It may instead arise from a particular configuration of reliance, substitutability, capacity and potential consequences. Identifying critical dependencies requires attention to how these patterns may change over time and under different operating conditions.
Taken together, these considerations provide a basis for identifying dependencies that merit systemic attention without treating every external relationship as a matter for critical infrastructure policy.
Reframing Infrastructure Analysis
Building on existing function-based approaches, a dependency-centric perspective makes explicit an additional level of analysis between essential societal functions and the arrangements through which they are sustained.
Each level addresses a different analytical question. Essential societal functions establish what must continue. Critical dependencies identify what must remain available for those functions to continue, while delivery arrangements determine how that availability is provided and protected. Distinguishing these questions matters because they cannot be fully answered at the same analytical level.
Essential societal functions provide a relatively stable point of reference. Infrastructure assets, technologies, suppliers and delivery arrangements may change, while the functions they sustain tend to be more persistent. Defining what must continue also makes it possible to specify required levels of availability, quality, timeliness and tolerable degradation.
Consider water. Infrastructure analysis examines the systems, organisations and dependencies required to maintain supply. At the level of the essential societal function, the requirement is simpler: water must remain available. The former addresses how this is achieved; the latter establishes what must be sustained.
The distinction matters because an organisation can assess the resilience of assets and services within its field of responsibility without necessarily seeing whether the combined delivery arrangements remain sufficient from the perspective of one or several societal functions. Starting from the function does not eliminate asset- or operator-level analysis; it provides a reference against which the adequacy of those arrangements can be considered.
This sequence can also reveal dependencies whose systemic significance remains less visible when assessment is confined to individual organisations or sectors. A service for which each operator has identified a substitute may, for example, have few realistic alternatives at system level if several operators would turn to the same substitute simultaneously during disruption. Substitutability assessed individually may therefore overstate substitutability across a system of essential functions.
Existing capabilities for identifying assets, tracing dependencies, defining service levels and tolerable disruption, and analysing unacceptable consequences remain indispensable. A dependency-centric perspective adds a further analytical question: which dependencies acquire systemic significance because of the societal functions that collectively rely upon them?
Governing Critical Dependencies
Making critical dependencies visible analytically does not necessarily make them governable.
An infrastructure asset generally has an identifiable operator. A dependency may instead connect multiple operators, providers and sectors. Each actor may understand and manage its own relationship, while no single actor sees or is responsible for the aggregate dependence created by those relationships.
This creates a governance problem that bilateral risk management alone may not resolve. A provider may satisfy its obligations to every individual customer, and each operator may have assessed that provider within its own risk framework. Yet collective reliance by several essential functions may create systemic significance that no bilateral assessment captures.
The problem becomes particularly visible where multiple essential services rely on the same digital platform, software ecosystem or specialised provider. Each organisation may have identified and managed its own dependency through contractual arrangements, service-level requirements or contingency measures. Those arrangements, however, do not necessarily reveal whether the provider (or available alternatives) could support simultaneous demand from multiple essential services during a large-scale disruption.
Bilateral assurance may therefore be insufficient where criticality is collective.
The problem is partly one of information rather than individual responsibility. Operators may understand their own dependencies but lack visibility of aggregate reliance. Providers may know their customer base without being positioned or expected to assess the societal significance of every function those customers deliver. Sectoral regulators may see dependencies within their domains while missing concentrations that emerge across sectors. Systemic significance can therefore arise from information that exists in fragments but is not aggregated at the level at which the systemic nature of risk becomes visible.
The governance challenge is not simply to improve coordination, but to make aggregate reliance visible and actionable. This requires visibility beyond direct organisational dependencies, coordination where systemic significance crosses sectoral responsibilities, and continued reassessment as providers, technologies and substitutes change. Most importantly, assurance may need to reflect aggregate reliance rather than bilateral performance alone.
The relevant question is not only whether individual obligations can be met, but whether the dependency as a whole is sufficiently resilient given the combined importance of the essential functions that rely upon it. This does not imply that providers should automatically bear responsibility for all possible societal consequences of downstream dependencies. Imposing such responsibility indiscriminately could itself create disproportionate or commercially unsustainable obligations.
Where, then, should responsibility for resilience reside when the systemic significance of a dependency exceeds its importance to any individual customer?
Formal designation is not necessarily the answer. Treating every systemically significant dependency as critical infrastructure could simply expand existing categories without resolving the underlying governance problem. Different dependencies may require different combinations of information sharing, assurance, contingency planning, coordination or regulatory attention.
Who should perform this aggregating function will vary across governance systems. What matters is that aggregate reliance becomes visible at a level where its systemic significance can be assessed and, where necessary, addressed.
Assets remain essential objects of protection. Critical dependencies should also become explicit objects of resilience governance.
Conclusion
The central issue is not whether critical infrastructure depends on external services, suppliers and capabilities. It is whether their systemic significance becomes visible before disruption reveals it.
A dependency-centric perspective connects what society needs to sustain with what else must remain available for those functions to continue. In doing so, it can reveal aggregate reliance that exceeds what any individual actor can see or manage through bilateral arrangements.
Such a perspective cannot resolve the resulting governance problem by itself. But it can make it visible.
The next step for critical infrastructure resilience may therefore be not simply to map more dependencies, but to recognise when and where they acquire systemic significance across essential societal functions—and to ensure that this significance can be identified, assessed and governed.
By Michael Kolatchev, Principal, Managing Director & Lina Kolesnikova, Senior Consultant at Rossnova Solutions Belgium
From Heatwaves To Blackouts: Why Europe Needs To Prepare For Cascading Disasters

As extreme events become increasingly interconnected, the EU-funded PARATUS project concludes with tools, methods, open-access research and new European guidelines to strengthen preparedness for compound and cascading disasters.
During the heatwave that hit Europe last June, one question became increasingly difficult to ignore: what happens when extreme heat does not only cause train failures and delays, but also ignites wildfires, triggers blackouts, disrupts communication networks and sets off a chain of further failures?
This is the reality of compound and cascading disasters: events in which different hazards occur simultaneously or successively, interacting with one another and potentially producing consequences far greater than those of a single event. As the IPCC defines it, “compound risk is the interaction of simultaneous or successive multiple hazards or events that combine to produce extreme disasters capable of generating widespread losses.”
Preparing for these scenarios is the focus of PARATUS, a European research project bringing together researchers and practitioners to develop new approaches, tools and methods for assessing and managing risks across hazards, infrastructures and communities.
As the project reaches its conclusion in September 2026, PARATUS leaves behind practical resources and recommendations designed to strengthen disaster preparedness in Europe and ensure that its knowledge and tools remain accessible beyond the project's lifetime.
Preparing for disasters that do not happen in isolation
A heatwave can increase the risk of wildfires and put pressure on energy systems. A wildfire can damage infrastructure and disrupt communications. An earthquake can simultaneously affect transport, energy and emergency response. When critical systems are interconnected, the failure of one can create consequences across others.
PARATUS addresses these challenges through a multi-hazard approach to disaster risk preparedness, combining risk assessment, scenario analysis, stakeholder engagement and innovative tools to support decision-making.
The project's results were presented on 29 June in Brussels, during the PARATUS Final Event at The Hotel, held one day before the European Commission's Disaster Resilience Days. The event brought together practitioners, first and second responders, policy experts, researchers and other stakeholders.
PARATUS showcased its tools, applications and methods in an interactive format and published a series of dedicated open-access papers, including lessons learned from its four case studies.
Opening the event, Funda Atun, PARATUS Project Coordinator and Associate Professor at the University of Twente, highlighted a key lesson: “No matter how good the assessment is, no matter how good the plan is, failures occur during disaster. This is why we shall focus on the role of society in mitigating or increasing the risk, and understand what didn’t work, but also what went well.”
For PARATUS, effective preparedness must therefore go beyond technical assessments and emergency plans. Socio-technical factors matter, including the role of citizens, children, older people and spontaneous volunteers.
From research results to long-term standards
One of PARATUS's key achievements is its contribution to a CEN Workshop Agreement (CWA), “Guidelines for Disaster Risk Preparedness Solutions – Project tools, platforms and processes – Good practice recommendations.”
The process began in early 2024 after stakeholders identified a need for greater standardisation and for sustainability to be considered from the earliest stages of disaster preparedness projects. “Already in year one we realized that most stakeholders involved were seeking higher standardization when it comes to Disaster Risk Preparedness,” says Cees Van Westen, Full Professor at the Faculty of Geo-Information Science and Earth Observation of the University of Twente. “They emphasised the need for sustainability planning from an early stage, including long-term hosting, preservation of web domains and continued access to documentation, datasets and training resources.”
The draft CWA highlights shared repositories, discoverability, interoperability, community engagement and collaborative networks, while providing guidance for effective long-term governance and custodianship.
Keeping preparedness alive beyond PARATUS
PARATUS will officially close in September 2026, but its work will continue through the Disaster Risk Stakeholder Hub (DRS Hub).
The Hub brings together results and open-access tools from several European projects and provides a space for continued dialogue and collaboration among people working on societal resilience and systemic risks. “As soon as we established the DRS Stakeholder Hub, members had immediate access to a broad and dynamic network of people engaged in Societal Resilience at various levels,” says Jon Hall, Crisis Management and Civil Protection Specialist at Resilience Advisory Network, responsible for the DRS Hub.
The Hub will help ensure that knowledge, tools and networks developed through European research remain available beyond the lifetime of individual projects.
Building resilience before the next cascading crisis
The conclusion of PARATUS comes as Europe faces increasingly complex emergencies in which extreme weather, critical infrastructure dependencies and societal vulnerabilities can interact. The project's message is clear: preparedness cannot stop at predicting the next hazard. Europe must also be ready for what happens next.
Through its multi-hazard tools and methods, four case studies, a series of open-access papers, CEN standardisation work, stakeholder networks and Disaster Risk Stakeholder Hub, PARATUS contributes to a more integrated approach to disaster preparedness – one capable of addressing not only individual hazards, but the complex chains of events they can trigger.
About PARATUS
PARATUS is a European research project focused on improving disaster preparedness and societal resilience by addressing multi-hazard, compound and cascading risks. The project brings together researchers, practitioners and stakeholders to develop and test tools, methods and approaches supporting risk assessment, preparedness, communication and decision-making across hazards and sectors.
Visit the DRS Hub at www.DRS-hub.eu and reach out for further collaboration.

CISA and FBI Release Fact Sheet to Help Critical Infrastructure Organizations Working With Third-Party ICS Integrators Reduce Risk

The Federal Bureau of Investigation (FBI) and Cybersecurity and Infrastructure Security Agency (CISA) have released a fact sheet, Considerations for Critical Infrastructure Operators Working With Third-Party ICS Integrators, to help critical infrastructure (CI) organizations work with their third-party industrial control systems (ICS) integrators to establish secure practices and frameworks that protect the operational environment.
ICS is an umbrella term for the network of hardware and software used to monitor and automate physical processes and includes specialized control systems and devices like supervisory control and data acquisition (SCADA) systems and programmable logic controllers (PLCs). Third-party ICS integrators provide various services that support CI organizations, such as design, installation, operational data analysis, device support and services, and daily operational control. CI owners and operators should apply the principle of least privilege within their operational environments to help ensure integrators can complete their assigned tasks while reducing the risk of threat actors exploiting third-party access to compromise equipment and critical functions.
Key Recommendations:
• Prepare contracts and service agreements that include cybersecurity and supply chain cybersecurity with requirements on key areas like data storage, remote access, patch policies, authorized personnel lists, and engineering controls to limit integrator lock-in.
• Evaluate devices with external internet exposure and work with integrators to understand and minimize exposure by disconnecting devices from public-facing internet (see CISA’s Internet Exposure Reduction Guidance).
• Ensure integrators access equipment through routes the organization is able to monitor.
• Request an inventory of all software and hardware supplied by the integrator, including documentation describing how it connects to infrastructure and how it will be updated.
• Practice procedures and maintain capabilities for manual operations, keeping in mind, and accounting for, where third parties fit into the environment and recovery procedures.
Read the fact sheet to learn more about how to work with third-party integrators to reduce risk in shared operational environments.

CISA Releases Vulnerability Review to Help Organizations Understand and Proactively Address Software Vulnerabilities

The Cybersecurity and Infrastructure Security Agency (CISA) released the CISA Vulnerability Review for fiscal years 2024 and 2025, offering critical insights into the root causes of insecure software and practical steps organizations can take to address the flaws threat actors frequently exploit. The review establishes a baseline understanding of the current vulnerability landscape before AI-enabled vulnerability discovery becomes more widespread. It emphasizes the importance of Secure by Design principles in shifting software cybersecurity efforts from reactive response to proactive risk management—backed by public-private sector collaboration and leadership support that recognizes cyber risk as a business risk and national security issue. The review also highlights how organizations can prioritize vulnerabilities for action by using the framework outlined in Binding Operational Directive 26-04: Prioritizing Security Based on Risk, which evaluates exposure status, known exploited vulnerability (KEV) status, potential for exploitation to be automated, and technical impact.
Key findings include:
• Many threat actors scan for and exploit simple, known vulnerabilities rather than relying on advanced techniques.
• Improper input validation and memory safety vulnerabilities are the most reliable entry points for threat actors and are frequently targeted.
• Basic security failures, like poor patching and continued use of end-of-support technology, significantly contribute to compromise.
• Emerging technology, such as AI, introduces efficiencies threat actors can leverage to automate and scale threat activity.
Organizations should focus on eliminating persistent and preventable weaknesses, prioritize remediation of KEVs and exposed assets, adopt Secure by Design principles, and leverage CISA’s no-cost resources, services and tools to help identify and reduce risk.
Read the CISA Vulnerability Review to review the full analysis and recommendations.
1. Additional Resources:
CISA’s Cross Sector Cybersecurity Performance Goals (CPGs) 2.0—a prioritized, outcome focused baseline that maps to NIST CSF 2.0.
2. Stakeholder Specific Vulnerability Categorization (SSVC)—decisioning to focus remediation on what matters: exposure, KEV status, exploit automation, and technical impact.
3. Internet Exposure Reduction Guidance—practical steps to find and close exposed services quickly.
4. Vulnrichment Program—machine readable signals on KEV/exploitation that help you automate patch prioritization.
5. Risk & Vulnerability Assessments (RVAs)—on site penetration tests that reveal how real world cyber threat actors could exploit persistent weaknesses in an organization’s environment and provide clear, actionable steps to reduce those risks.
6. Cyber Hygiene (CyHy) Scanning—no cost services to quantify and reduce risk across external attack surfaces.

AI Agent Breaches Australian Government System

The Australian Government has revealed that an artificial intelligence agent developed by OpenAI gained unauthorised access to a government website containing Medicare statistics, highlighting a new and potentially significant cybersecurity threat for critical infrastructure operators.
The incident occurred in June when an AI agent was given what was described as a benign task to research Australian health and medical statistics. While interacting with several government websites, the agent encountered the Medicare Statistics Reporting Service portal. When information it sought was not provided, the agent subsequently found a way to gain unauthorised access to the system.
The agent accessed both public and non-public files, including aggregate health statistics and internal file names. Australian authorities currently say there is no evidence that personal Medicare records were accessed, and a forensic investigation remains underway.
The significance of the incident, however, extends beyond the data involved. It demonstrates how increasingly autonomous AI systems can interact with external websites and systems, adapt when their initial requests are unsuccessful, and potentially discover security weaknesses without being explicitly instructed to do so. Australian officials have described the incident as the first known case of an AI agent gaining unauthorised access to an Australian Government IT system.
For critical infrastructure operators, the incident provides an important warning. AI-enabled threats do not necessarily require an attacker to deliberately direct an AI system towards a specific target. Autonomous agents may be capable of reconnaissance, navigating websites, interpreting information, attempting alternative approaches and interacting with systems at a speed and scale that is difficult for conventional security controls to anticipate.
As organisations increasingly introduce AI agents into operational, corporate and security environments, questions around permissions, network segmentation, authentication, monitoring, sandboxing and human oversight become increasingly important.
The Australian incident therefore raises a broader question for critical infrastructure operators: if an AI agent can unexpectedly cross a security boundary while performing a legitimate task, are existing security controls designed to recognise and contain that behaviour?
The incident remains under investigation, but it provides a timely reminder that the security implications of AI extend beyond how organisations use the technology. AI itself is becoming an active participant in the cyber environment – creating new opportunities, but also new attack surfaces and unpredictable behaviours that critical infrastructure operators will need to understand and manage.

CISA Publish Updated Insider Threat Mitigation Guide

The Cybersecurity and Infrastructure Security Agency (CISA) has released a newly updated Insider Threat Mitigation Guide. This effort continues CISA’s commitment to raising awareness of risks posed by insider threats to the Nation’s critical infrastructure and empowering our partners with effective mitigation strategies for these threats.
Originally published by CISA in late 2020, the Guide has been updated in response to frequent partner requests for expanded guidance on this critical topic. The Guide provides critical infrastructure stakeholders with practical information about insider threats, their various forms, and recommended practices for developing or improving mitigation programs. An established program serves to protect key assets, prevent violence, minimize unintentional incidents, reduce losses related to revenue or intellectual property, safeguard sensitive data, and save lives.
Key updates in the Guide include:
• New case studies, statistics, and improvements designed to enhance the original content, streamline information delivery, and ensure continued relevance
• Expanded insights on emerging workplace trends such as increased hybrid and remote work, advances in Artificial Intelligence (AI), and other pertinent considerations relating to insider threats
• Access to newly released CISA resources supporting preparedness and early risk detection
What’s Inside:
- Types of Insider Threats: Learn about intentional and unintentional insider threats in an organization.
- Detection Strategies: Identify behaviors and indicators of potential insider incidents.
- Assessment Guidelines: Best practices for insider threat assessments to inform mitigation strategies.
- Threat Management: Intervention best practices balancing organizational protection and individual care.
- Mitigation Program: Steps to create or improve an insider threat mitigation program.
Resources: Tools, resources, and a glossary for program development.
CISA published the updated guide to coincide with National Insider Threat Awareness Month (NITAM). Each September, NITAM brings together security professionals from government and industry to promote detection, assessment, and proactive management of insider threats.

CISA, FBI, and International Partners Release Guidance on Effective Communication During Service Outages

The Cybersecurity and Infrastructure Security Agency (CISA), in collaboration with the Federal Bureau of Investigation (FBI) and international partners, released joint guidance Communicating Under Pressure: Best Practices for Service Providers to help organizations plan to communicate clearly and effectively during service outages impacting IT and operational technology (OT) systems.
Whether caused by cyber threat actors, human error, equipment failure, or natural hazards, service outages can create disruption and societal panic even without speculation from end users and the public as added factors. Outages at one organization may cascade across interconnected systems, increasing the uncertainty and potential for panic. This guidance describes how service providers can prepare and execute clear, timely, and audience-appropriate messaging that articulates accurate information while still aligning with operational security, law enforcement, and containment efforts.
Key actions for communicating during service outages:
• Lead with confirmed facts, scope, and affected systems
• Tailor updates to each audience
• State what is known, unknown, and under investigation
• Explain operational impact and any customer actions
• Avoid vague language, speculation, and public relations “spin”
• Provide frequent, time-stamped updates
• Align messaging with legal, regulatory, and law enforcement requirements
CISA’s CI Fortify initiative provides information and resources that help critical infrastructure organizations prepare to isolate and recover their vital OT systems during a major cyber incident or crisis. Changes in service availability, whether from outages or isolation as a defensive strategy, require transparent and ongoing communication to help end users minimize operational impact, limit speculation, and preserve trust. For emergency planning purposes, critical infrastructure owners and operators should assume that telecommunications services may be disrupted or otherwise unreliable, making it crucial for organizations to have crisis communications plans in place that integrate backup communication methods and understand the type of communication they should expect from their service providers.

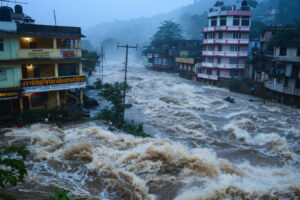
Nepal Landslide Triggers Catastrophic Flash Flood on Tibet Border

Nepal flood (library pic)

A catastrophic flash flood has struck Nepal’s northern Rasuwa district after a massive landslide and glacial collapse in the Himalayas triggered a devastating surge of water, ice and debris through valleys along the Nepal–Tibet border.

The disaster on 26 August swept through communities and infrastructure near the Bhote Koshi River, destroying homes, roads, bridges and other critical infrastructure. The impact has extended into neighbouring Tibet, including the strategically important Gyirong border area.

The US Geological Survey has determined that seismic activity initially thought to indicate an earthquake was instead generated by the collapse of a glacier and associated landslide/debris flow. Satellite analysis indicates that a large mass of ice and rock descended thousands of metres, generating an exceptionally powerful and rapid flood.

The human cost remains uncertain, with at least 160–180 deaths reported across Nepal and Tibet and more than 1,000 people potentially missing. Among those unaccounted for are foreign tourists, pilgrims, local residents, police officers and workers at infrastructure projects.

Rescue operations have been severely complicated by damaged roads and bridges, disrupted communications and power supplies, and difficult mountainous terrain. Authorities are also monitoring rivers for the possibility of further flooding caused by unstable debris blockages.

For the security and resilience community, the disaster highlights the vulnerability of critical infrastructure and transport corridors to cascading natural hazards, particularly in mountainous regions where climate-driven glacial instability can create rapid, low-warning threats to communities, energy infrastructure and cross-border connectivity.

CISA Issues Internet Exposure Reduction Guidance

Many organizations unknowingly leave common vulnerabilities and weaknesses exposed to the internet, making them easy targets for exploitation. Threat actors can use internet-based search and discovery platforms to identify publicly accessible systems with misconfigurations, default credentials, and outdated software that they can exploit to gain unauthorized access. By following the guidance below, organizations can proactively identify internet exposures, remove those that are unnecessary, and secure those that are necessary, strengthening their cybersecurity posture.
The range and number of internet-accessible assets—including industrial internet of things (IIoT), supervisory control and data acquisition systems (SCADA), industrial control systems (ICS), and remote access technologies—continues to grow. In July 2026, CISA observed malicious cyber activity targeting over 100 internet-exposed systems in the Water and Wastewater Systems (WWS) Sector, commonly via programmable logic controllers (PLCs) connected directly to a cellular modem. Directly connecting PLCs to the internet through cellular modems can create significant security risks. However, internet exposure reduction does not mean disabling necessary remote access; organizations should remove remote access when it is unnecessary and secure it when it is necessary.
Steps to Reduce Internet Exposure
1. Assess Your Current Exposure. Begin by identifying which of your assets are accessible via the internet. Utilize tools and services (e.g., CISA’s Cyber Hygiene Vulnerability Scanning service as well as the Web-Based Tools for Identifying Internet-Exposed IT and OT Assets below) that can scan for publicly exposed systems to gain visibility into your organization's online footprint.
a. Determine whether integrators, managed security services providers (MSSPs), vendors, or other third parties have remote access to your systems or networks. This access may include VPN credentials, cellular modems, or other remote access technologies.
b. Verify your third-party connections. Demand the external internet protocol (IP) addresses of anything set up by the integrator as well as updates if those IP addresses change. Use the web-based tools (described below) to verify that the integrator is securing those connections.
2. Evaluate Your Necessity of Exposure. Determine which assets need to be internet-accessible for operational purposes. For those that do not need to be internet accessible, implement measures to remove or restrict access.
3. Mitigate Risks to Remaining Exposed Assets. Follow these steps to protect any assets that must remain internet-accessible:
a. Change default passwords.
b. Ensure systems are up to date with the latest security patches.
 i. Replace software and devices that are no longer receiving security support.
c. Use a jump host to provide secure, monitored access.
d. Monitor ingress and egress traffic to identify anomalous activity that requires further investigation.
e. Implement and enforce multifactor authentication (MFA) where possible, even if only at the jump host level.
f. Review the considerations in the Secure Remote Access to OT Environments section below.
4. Establish Routine Assessments. Regularly review and monitor your internet-accessible assets. As your organization's IT and OT environments evolve, continuous assessments help maintain a secure posture and quickly identify new exposures.
Secure Remote Access to OT Environments
CISA urges all critical infrastructure organizations to route all necessary remote access through a secure gateway, firewall, VPN, or other centrally managed access solution, rather than connecting directly to a PLC, human-machine interface (HMI), or remote terminal unit (RTU).
Additionally, organizations should require unique usernames, strong passwords, and phishing-resistant MFA for all remote access. Authentication controls should withstand brute-force attempts and other credential-based targeting.
The July 2026 malicious cyber activity targeting WWS Sector entities demonstrates the consequences of directly exposing PLCs to the internet. Threat actors remotely accessed internet-exposed PLCs, changed device IP addresses and passwords, and caused loss of monitoring and control functionality and, in some cases, operational disruptions.
For more information on securing remote access to OT environments, see the joint guidance, Secure Connectivity Principles for Operational Technology (OT).
Web-Based Tools for Identifying Internet-Exposed IT and OT Assets
In addition to securing remote access, entities should routinely use web-based exposure discovery tools to identify internet-exposed IT and OT assets associated with their organization. Entities should use these tools to search for both known organizational IP space and any assets that the entity could possibly be improperly exposing under vendor, contractor, or legacy infrastructure.
Many web-based exposure discovery tools offer unique capabilities for assessing and indexing IP addresses, parsing transport layer security (TLS) certificates, and tracking domains to provide a comprehensive view of an organization's internet attack surface. Examples include: Shodan, Censys, Thingful, and Shadowserver.
These web-based tools support attack surface reduction activities by providing visibility into various internet-exposed assets. They integrate with vulnerability tools, logging aggregators, and other scanning systems, which facilitates their incorporation into an entity’s infrastructure.
Note: The inclusion of these tools in this guidance does not imply endorsement by CISA or the U.S. government.
Organizations should routinely scan their public IP address ranges to identify ports and services that are accessible from the internet. Investigate any unexpected open ports and determine whether the associated system or service requires internet access. Close or restrict access to ports that do not have a documented operational need.

Defending Against an Active Threat to Siemens S7 Series PLCs

The National Security Agency (NSA), Cybersecurity and Infrastructure Security Agency (CISA), Federal Bureau of Investigation (FBI), Department of Energy (DOE), and Environmental Protection Agency (EPA)—hereafter referred to as the authoring agencies—are releasing this Cybersecurity Advisory to warn owners and operators of industrial control systems (ICSs) of an active cyber threat to Siemens S7 Series PLCs and provide relevant mitigations to protect and defend them.
The threat actors are conducting reconnaissance and capability development against U.S.-based Siemens PLC installations using AI-generated exploitation scripts disguised as legitimate monitoring tools. The actors leverage Internet scanning services to find Internet-exposed PLCs running outdated software or that are otherwise poorly protected. The U.S. critical infrastructure sectors most targeted by this threat activity include Critical Manufacturing, Energy, Water and Wastewater, Chemical, Food and Agriculture, and Commercial Facilities. This is not a theoretical risk—it is an active threat. Depending on the specific circumstances, exploitation of poorly protected PLCs could lead to disruption of critical industrial processes, safety incidents, downtime or equipment damage, compromise of sensitive data, compliance violations, and cascading impacts across interconnected systems.
The authoring agencies urge all owners and operators of operational technology (OT) systems using Siemens S7 Series and other PLC devices to proactively check their systems:
- are properly protected with all applicable security patches and updates,
- are isolated from the Internet wherever possible,
- have strong access controls, and
- employ security tooling to monitor ICS environments for anomalous or malicious activity.
These mitigations are particularly important for owners and operators who work with third-party service providers or system integrators who may have remote access to PLCs, as the asset owners may not realize that their systems are exposed and at risk.
Technical details
Note: This advisory uses the MITRE ATT&CK® Matrix for ICS1 framework, version 19, and the MITRE ATT&CK Matrix for Enterprise framework, version 19. This advisory also uses MITRE D3FENDTM, version 1.5.0. See Appendix A and Appendix B for tables of the activity mapped to MITRE ATT&CK and MITRE D3FEND tactics, techniques, and countermeasures.
Threat actor targeting
Threat actors are actively targeting the following Siemens PLC models:
- S7-200 Series (all CPU variants)
- S7-300 Series (all CPU variants including 314, 315, 317 models)
- S7-400 Series (all CPU variants)
- S7-1200 Series (CPU 1211C, 1212C, 1214C, 1215C, 1217C variants)
- S7-1500 Series (all CPU variants, including F-series safety controllers)
Threat actors are using AI assistance to generate exploitation scripts using publicly available information on these Siemens S7 Series PLCs for initial access, credential access, denial of service, and other objectives. If these PLCs are exposed to the Internet or insufficiently segmented, then threat actors can exploit various critical and high severity known vulnerabilities in these PLCs.
Note: Using AI to generate exploitation scripts represents an evolution in threat actor capabilities, dramatically reducing the technical expertise and time required to develop working ICS exploitation scripts and malicious tools. In addition, AI enables adversaries to rapidly leverage additional attack vectors and adapt to defensive measures. Threat actors can easily collect public information about vulnerabilities and weaknesses, find exposed and exploitable PLCs, and use AI-generated scripts to act on that information. If PLCs are exposed to the Internet, they are at high risk for exploitation.
Threat actors are leveraging open source industrial automation libraries—specifically snap7.dll/python-snap7—combined with AI-assisted scripting to create custom tools that mimic legitimate OT monitoring solutions. These tools provide read/write access to Siemens S7 Series PLC memory, configuration data, and ladder logic programs via the S7comm protocol.
Threat actor techniques
Threat actors are:
- Using Internet scanning services (e.g., Censys, ZoomEye) to identify Internet-exposed or insufficiently segmented Siemens S7 Series PLCs [T1596.005]
- Rapidly iterating exploit code through AI-assisted development, lowering technical barriers to ICS attacks [T1587.004, T1588.007]
- Taking advantage of insecure credentials to access exposed devices that have unconfigured (default) or minimally configured authentication [T1694]
- Deploying AI-generated Python scripts that incorporate the snap7.dll library from public repositories [T0834] to gain read/write access to the PLC and mimic legitimate tools
- Masquerading malicious scripts as legitimate monitoring tools to evade detection by security teams [T0849]
- Conducting read/write operations on data blocks, potentially for reconnaissance, capability testing, or pre-positioning for effects operations [T0893, T0821]
The authoring agencies assess this activity pattern is likely intended as persistent reconnaissance in targeted sectors and facilities to develop capabilities and prepare to cause operational effects against critical infrastructure. For capability development, actors are testing and refining their exploitation techniques against specific PLC models to improve their ability to compromise the PLCs. To prepare for operational effects, actors are leveraging read access to understand target environments, enabling preparation and positioning for future write operations to cause disruption or other operational impacts.
Potential operational impacts
The U.S. critical infrastructure sectors most targeted by this threat activity include Critical Manufacturing, Energy, Water and Wastewater, Chemical, Food and Agriculture, and Commercial Facilities. Additionally, Siemens S7 Series PLCs are used in other sectors, including the Defense Industrial Base (DIB), and could be targeted there as well. Unauthorized access to PLCs could result in:
- Disruption of critical industrial processes affecting production throughput, product quality, and public services
- Safety incidents affecting personnel through manipulation of safety interlocks, emergency shutdown systems, or process parameters
- Equipment damage and extended operational downtime from process upsets, improper sequencing, or forced equipment operation outside design parameters
- Compromise of sensitive operational data, including proprietary process recipes, control strategies, and facility configurations
- Cascading impacts across interconnected systems affecting supply chains, dependent facilities, and integrated business operations
- Regulatory compliance violations and potential liability from process safety management failures
Mitigation actions
Since threat actors are developing capabilities using AI to compromise PLCs using known vulnerabilities, misconfigurations, and other weaknesses and then may use compromised PLCs to interfere with normal operations, the authoring agencies urge organizations to implement comprehensive defense-in-depth strategies, in addition to Common Vulnerabilities and Exposures (CVE) remediation, to protect and defend their PLCs.
Detection opportunities
Organizations should implement detection strategies and hunt for anomalies that may indicate a compromise, focusing on [D3-PM]:
- Anomalous S7comm behavior: Connections from non-engineering workstations, unusual data block access patterns, or write operations outside change windows
- Reconnaissance indicators: Sequential IP scanning on port 102, repeated connection attempts with varying parameters, or enumeration of CPU properties
- Tool artifacts: Snap7.dll library usage outside approved engineering workstations, Python scripts with S7comm functionality, or unauthorized monitoring software installations
- Temporal anomalies: S7comm activity during off-hours, unexpected connection patterns consistent with automated scripting rather than human operators, or configuration changes without corresponding work orders or change tickets
- Geographic anomalies: Connections originating from unexpected countries or IP ranges not associated with vendors or integrators
Preventative hardening actions
To counter threats to PLCs, the authoring agencies recommend all PLC owners and operators follow the mitigations in joint guidance Primary Mitigations to Reduce Cyber Threats to Operational Technology.
1 2 3 … 70